BotMaker
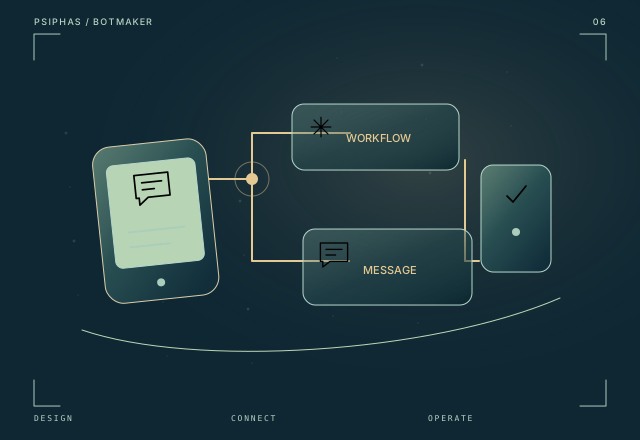
A WhatsApp automation workspace that brings configurable bot behavior, workflow design, and operational management into one SaaS dashboard.
Explore BotMakerAI-assisted legal technology
A legal knowledge workspace that connects mixed case documents, local-first retrieval, and answers with a visible path back to their evidence.
Project status
Built
Technology stack
Engineering focus
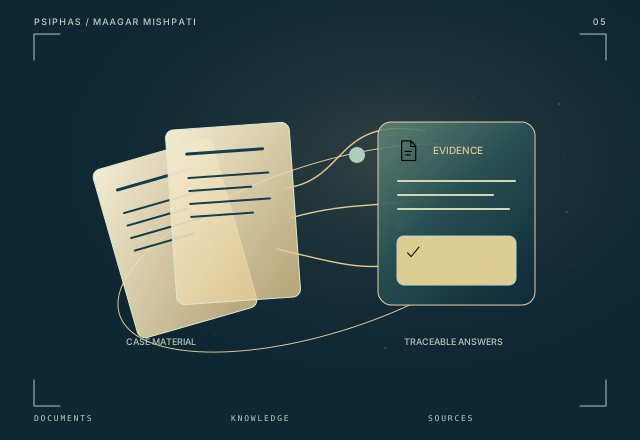
Maagar Mishpati connects document research with the evidence behind it. Local embeddings, hybrid retrieval, and a structured evidence ledger support research across actors, places, events, and facts—while preserving links back to case material.
01 / Context
Legal research involves connecting people, places, events, and facts across mixed documents. A useful answer must preserve the relationship to the evidence behind it, especially when a question depends on exact counts or relationships spread across a case folder.
02 / The system
Maagar Mishpati turns PDFs, Word documents, spreadsheets, and message exports into a searchable knowledge layer. Local embeddings and hybrid retrieval connect a research question with relevant case material; a language model writes the final answer. Source-linked facts and an evidence ledger support research that needs a path back to the documents, including structured counting questions.
03 / Capabilities
Research spans PDFs, Word files, spreadsheets, and message exports within case folders.
Local embeddings and hybrid retrieval connect a question with relevant case material before the final answer is written.
Source-linked facts and an evidence ledger preserve a path from research output back to the documents behind it.
04 / System map
This conceptual sequence explains how the project’s main capabilities connect.
Mixed case documents feed a knowledge layer of entities, events, and facts.
Local embeddings and hybrid retrieval support the research query.
The language model writes from the retrieved material.
Source links and the evidence ledger keep the research connected to case documents.
05 / Scope & status
The desktop application is built and awaiting its next deployment opportunity.
Continue exploring
A WhatsApp automation workspace that brings configurable bot behavior, workflow design, and operational management into one SaaS dashboard.
Explore BotMaker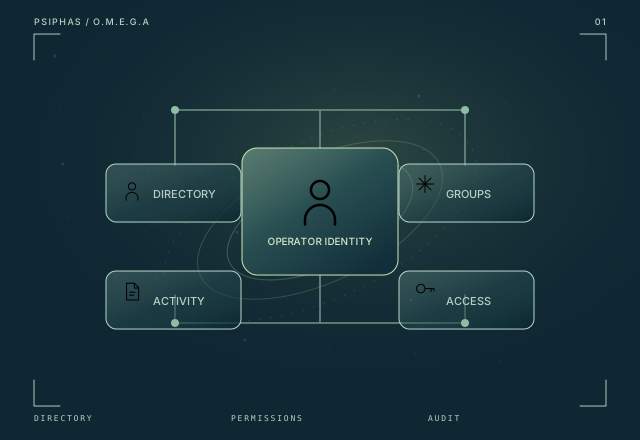
A unified Active Directory workspace for guided administration, operator-based permissions, and traceable enterprise identity operations.
Explore O.M.E.G.A