O.M.E.G.A
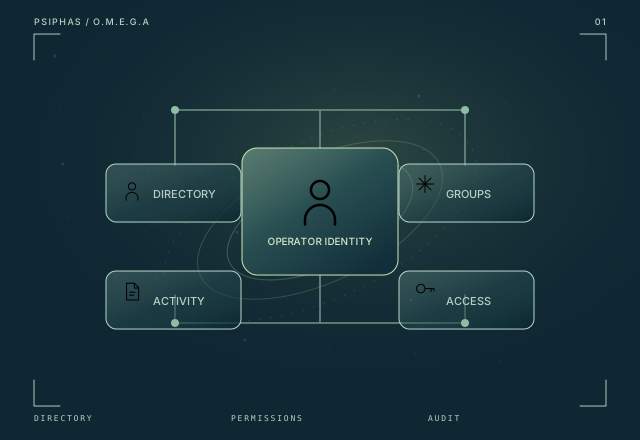
A unified Active Directory workspace for guided administration, operator-based permissions, and traceable enterprise identity operations.
Explore O.M.E.G.ASecurity research
A multi-agent security research engine that connects parallel investigations, target-specific testing, and benchmark evidence.
Project status
CVE benchmarking
Technology stack
Engineering focus
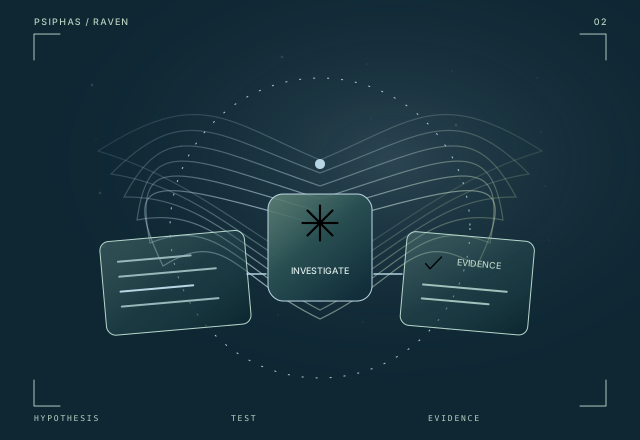
RAVEN connects exploratory reasoning with concrete testing. AI agents investigate a target, form hypotheses about possible vulnerabilities, and write tests tailored to those hypotheses—bringing the investigation and its evidence into one research workflow.
01 / Context
Security research becomes useful when a suspicion can be turned into a concrete test. RAVEN explores that transition: agents examine the target, develop competing hypotheses, and investigate the behavior that would support or challenge those hypotheses.
02 / The system
RAVEN coordinates multiple AI agents across codebases, repositories, and web applications. Agents form vulnerability hypotheses, write tailored attack tests, and run those tests as part of the investigation. The project’s current CVE benchmarking phase is intended to measure detection performance before its planned open-source publication.
03 / Capabilities
Multiple AI agents investigate different hypotheses about a codebase or application.
The platform writes tests for the specific weaknesses under investigation, connecting reasoning with executable validation.
CVE benchmarking provides a framework for evaluating detection performance. Publication is planned after the project’s benchmarking goals are met.
04 / System map
This conceptual sequence explains how the project’s main capabilities connect.
Agents investigate the supplied codebase, repository, or web application.
Different investigation paths propose possible weaknesses.
Tests are written and run for the hypotheses being explored.
Results feed the investigation and the ongoing benchmark evaluation.
05 / Scope & status
The platform is built and undergoing CVE benchmarking. Open-source publication is planned after its benchmarking goals are met.
Continue exploring
A unified Active Directory workspace for guided administration, operator-based permissions, and traceable enterprise identity operations.
Explore O.M.E.G.A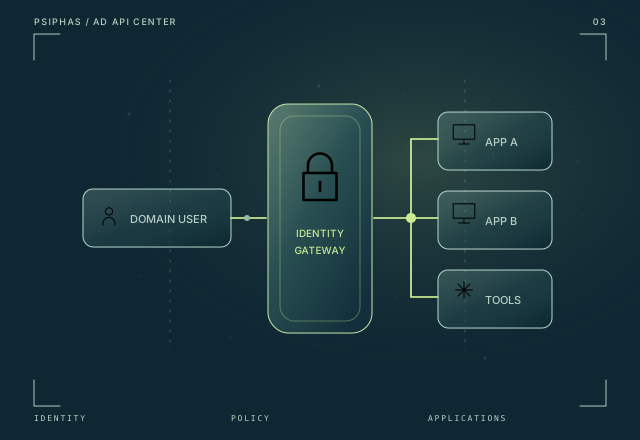
A shared authentication foundation for internal applications, connecting Active Directory identity with origin-bound profiles and application-specific access rules.
Explore AD API Center